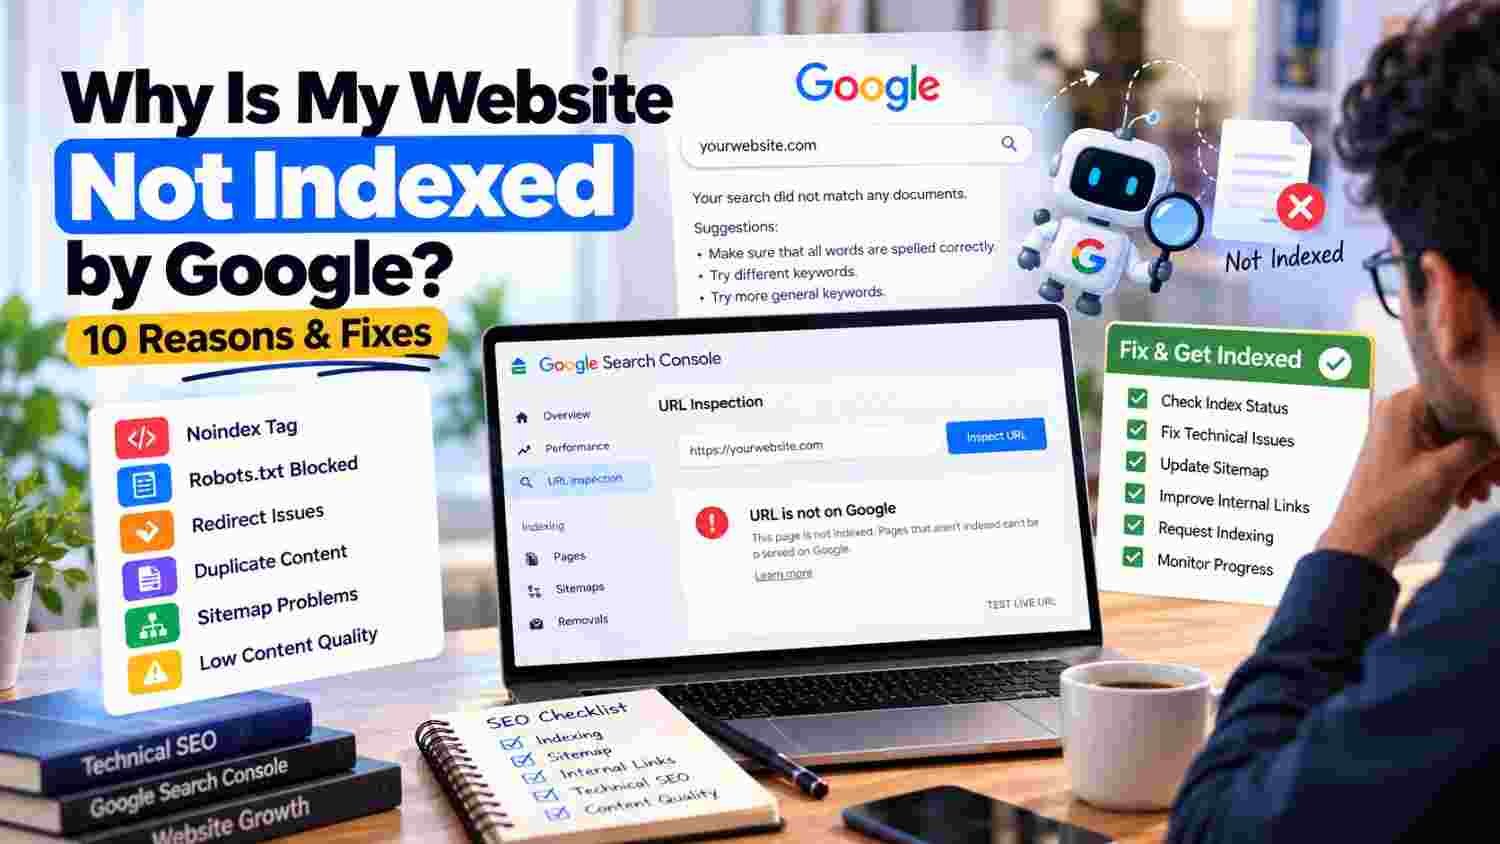
Why Is My Website Not Indexed by Google? 10 Reasons & Fixes
- Home
- Why Is My Website Not Indexed by Google? 10 Reasons & Fixes
Published: October 6, 2026
Last Updated: October 6, 2026
Website Not Indexed by Google usually means Google knows about your website or page but has not added it to its search index, or Google cannot currently access it properly. A page must be accessible, return a successful response, and contain indexable content before it can be considered for indexing. Even then, Google does not guarantee that every page will be indexed. Google's Page Indexing documentation
The first step is to find out why the page is not indexed. Google Search Console's URL Inspection tool can show the index status of a specific URL, while the Page Indexing report helps identify larger patterns across a website.
A website or page may remain unindexed because Google cannot access it, the page has a noindex directive, it is blocked from crawling, it redirects elsewhere, it is a duplicate, it has technical errors, or Google has discovered or crawled it but has not selected it for indexing.
A simple troubleshooting flow is:
Check URL → Inspect Index Status → Find the Reason → Fix the Issue → Request Recrawl → Monitor
Google also explains that “Discovered - currently not indexed” means Google knows about the URL but has not crawled it yet, while “Crawled - currently not indexed” means Google has crawled the page but has not added it to the index.
A page can be accessible and remain unindexed.
Use URL Inspection to investigate a specific URL.
Check noindex, robots.txt, redirects, canonical tags, and server responses.
Make important pages easy to discover through internal links.
Keep your XML sitemap accurate and up to date.
“Discovered - currently not indexed” and “Crawled - currently not indexed” mean different things.
Requesting indexing does not guarantee immediate inclusion.
Repeatedly requesting the same URL will not make Google crawl it faster.
Fix the underlying problem before requesting another crawl.
Monitor indexing after making changes.
Indexing happens after Google finds a page, crawls it, processes its content, and decides whether to add it to Google's index. Only indexed pages are eligible to appear in normal Google Search results.
That means crawling and indexing are not the same thing.
A page may be:
Discovered but not crawled
or:
Crawled but not indexed
or:
Indexed
These different states require different actions.
For a quick check, you can search Google using:
site:yourdomain.com
You can also search for an exact page URL.
Google recommends these searches as a simple way to check whether important pages are already indexed, especially for smaller sites.
For a specific URL, however, the more reliable method is:
Google Search Console → URL Inspection → Enter URL
The URL Inspection tool gives you information about the URL's current index status and can also provide testing options.
Here are 10 common reasons to check.
A noindex instruction tells search engines not to include a page in search results.
It may be added intentionally or accidentally.
For example, a page under development might be set to:
noindex
and the setting may remain after launch.
Google recommends using noindex when you want to prevent indexing, while robots.txt is not the correct method for keeping a page out of the index. Google for Developers
Check the page's source or SEO settings.
Make sure important pages do not contain an accidental noindex.
A robots.txt file can prevent Googlebot from crawling specific URLs or sections of your website.
That can create indexing problems when important pages are accidentally blocked.
Google explains that blocking crawling with robots.txt does not necessarily prevent a URL from appearing in search, but it can stop Google from fetching the page's content.
Check:
yourdomain.com/robots.txt
Look for rules that block the page or important resources needed to render it.
Google requires the page to work successfully.
Google's technical requirements state that the page should return an HTTP 200 (success) status and contain indexable content. Server errors and client errors do not meet that requirement.
Possible causes include:
Server errors
Hosting problems
Temporary downtime
Access restrictions
Login requirements
Incorrect firewall settings
Use URL Inspection and check whether Google can access the page.
Also review your hosting and server logs if the problem continues.
A page that redirects somewhere else is generally not indexed as the original URL.
Google's Page indexing documentation lists redirect errors among reasons for pages not being indexed. These can include redirect loops, long chains, bad redirect URLs, or other redirect problems.
Check:
Old URL → Redirect → Final URL
Make sure the final destination works correctly and that unnecessary redirect chains are removed.
You may see:
Discovered - currently not indexed
This means Google knows the URL exists but has not crawled it yet.
Google explains that this can happen when Google has found the page but has postponed crawling it.
Make sure the page:
Is included in your XML sitemap
Has relevant internal links
Is publicly accessible
Is not blocked
Provides useful content
Do not repeatedly request indexing. Google says requesting a crawl multiple times for the same URL does not make it happen faster.
Another common status is:
Crawled - currently not indexed
This means Google has visited the page but has not selected it for indexing.
A technical check alone may not solve this.
Review the page for:
Duplicate content
Weak or thin content
Poor search intent alignment
Low-value pages
Similar pages competing with one another
Unclear page purpose
Google's Page indexing guidance specifically says that not every non-indexed page is necessarily an error; you need to examine the reason shown for the URL.
Google does not need to index multiple copies of essentially the same page.
For example:
https://example.com/page
and:
https://example.com/page?ref=123
may represent the same underlying content.
Google's indexing documentation lists duplicate and alternate pages among URLs that may not be indexed separately.
Check:
Canonical tags
URL parameters
Duplicate pages
Similar content
Alternate URL versions
Make sure the preferred page clearly identifies itself as the canonical version.
Google discovers URLs in multiple ways, including links and sitemaps. Important pages should be reachable through crawlable links.
A page that exists only in your sitemap but has no useful internal connections may be harder to discover and understand in the broader context of your website.
Link relevant pages together.
For example:
SEO Guide → Internal Linking Guide → Related Service Page
Use descriptive anchor text rather than generic phrases such as “click here.”
You can learn more from the Internal Linking Strategy guide on the Tulyarth DigiWeb blog.
A sitemap can help Google discover URLs, but it does not guarantee that those URLs will be indexed. Google's documentation describes sitemaps as a way to help discovery, not as a command to index every listed page.
Problems can include:
Redirecting URLs
Non-canonical URLs
Blocked URLs
Outdated URLs
Invalid sitemap files
Keep only useful, canonical URLs in your sitemap.
Then review the Sitemaps report in Search Console.
You can also read the XML Sitemap SEO guide for a detailed sitemap checklist.
Sometimes the page is technically accessible, but that still does not mean Google will index it.
Google's technical requirements explain that meeting technical requirements only makes a page eligible for indexing. It does not guarantee that the page will be indexed.
Review whether the page:
Answers a clear search intent
Adds useful information
Provides a distinct purpose
Avoids unnecessary duplication
Offers enough value for the topic
This is especially important when a website contains many pages covering very similar topics.
Use this troubleshooting process.
Open Google Search Console → URL Inspection and enter the affected URL.
Find out whether the page is:
Indexed
Discovered - currently not indexed
Crawled - currently not indexed
or affected by a technical issue.
Verify:
HTTP status
robots.txt
noindex
canonical
redirects
login restrictions
Google recommends URL Inspection for investigating individual pages and the Page indexing report for broader site-level patterns.
Make sure important pages have relevant internal links.
Confirm the preferred URL is present and accessible.
Address duplicate, weak, outdated, or poorly targeted content where appropriate.
After fixing the issue, use URL Inspection to request another crawl for the affected page. Google says crawling can take from several days to several weeks, and a request does not guarantee immediate inclusion.
There is no guaranteed indexing timeframe.
Google says crawling can take a few days to a few weeks, depending on the site and circumstances. It also states that requesting indexing does not guarantee instant inclusion.
Therefore, don't judge a newly published page after only a few hours.
Instead:
Publish → Make the page discoverable → Request indexing when appropriate → Monitor → Improve if needed.
No.
The URL Inspection tool lets you request a crawl for eligible URLs that you manage, but Google explicitly states that a request does not guarantee inclusion in search results.
Repeated requests for the same URL also do not make Google crawl it faster.
The better approach is to fix the actual issue first.
They can help Google discover important pages and understand the relationship between your site's content.
Google recommends standard crawlable links and says links are an important way for Google to find pages.
For example, a new blog can receive a relevant link from an older, established article.
That creates a clear path:
Existing Page → New Article → Related Service Page
No. An XML sitemap can help Google discover a URL, but it does not guarantee that Google will crawl or index the page.
This distinction matters.
A page may be:
In sitemap + accessible + crawlable
and remain unindexed.
Google explicitly says a sitemap is a helpful discovery mechanism, not a guarantee that Google will crawl or index every URL.
Repeated requests do not guarantee faster crawling.
Make sure important pages are not accidentally blocked.
Check your CMS and SEO settings after publishing.
Overlapping pages can create duplication and unclear page purpose.
Connect new pages to relevant existing content.
A sitemap helps discovery; it does not guarantee inclusion.
Search Console gives you two especially useful tools.
Use it when you want to investigate one specific URL.
Use it when you want to understand indexing patterns across many URLs.
Google says the Page Indexing Report shows pages Google knows about and the reasons some are not indexed, while URL Inspection is the tool for checking a specific page.
Together, these tools make indexing diagnosis much easier.
Indexing problems can involve both technical SEO and website development.
A proper diagnosis may require checking the page setup, URLs, redirects, internal links, sitemap, crawl access, canonical tags, and content structure.
For businesses facing website indexing or technical SEO problems, contact Tulyarth DigiWeb about your website's SEO requirements.
Website Not Indexed by Google does not always mean your website has a serious technical error.
The first step is to find the exact status Google reports. Then check access, noindex, robots.txt, redirects, canonical URLs, internal links, sitemaps, duplication, and content quality.
For a specific page, use URL Inspection. For broader website problems, use the Page indexing report.
Most importantly, remember that requesting indexing is not a guarantee. Google can take days or weeks to crawl a page, and some pages may remain outside the index even when they are technically accessible.
You may also find these articles helpful:
How to Choose a CMS for Your Business Website: A Practical Guide
XML Sitemap SEO: How to Create, Submit, and Optimize a Sitemap
Website Migration SEO Checklist: How to Move Your Website Without Losing Rankings
Internal Linking Strategy: How to Connect Your Website Pages for Better SEO
Landing Page Optimization: 15 Practical Ways to Get More Leads